Mmmmmmmm! Today we’re going to compare two methods of modeling Markov chains, in the context of the board game Monopoly. One method is Monte Carlo simulation (of which I’ve written about before). The other is transition matrix analysis, which has applications in communication systems or anything else where queues are involved.
The point isn’t just to learn about strategy in Monopoly — there are takeaways involving heuristics, and the distinction between static and dynamic analysis. Oh, and Markov chains.
Monopoly
The board game Monopoly was created by Charles Darrow in the early 1930s, based in part on Elizabeth Magie’s The Landlord’s Game. In case you’ve been stuck under a rock for the last ninety years, Monopoly is a game of real estate acquisition that consists of moving metal tokens around and around and around a square of forty spaces, trying to force your fellow players into bankruptcy. The game became a hit, and Darrow sold it to Parker Brothers in 1935.

Twenty-eight of those forty spaces are properties: the two utilities (Electric Company and Water Works), the four railroads — one in the middle of each board edge — and twenty-two “street” properties, divided into eight colored groups, on which houses and hotels can be built. We’re not going to talk about most of the game mechanics, but suffice it to say that the strategy of playing Monopoly depends on how likely it is to land on the various properties — because if you own a property, and someone else lands on it, then they are required to pay you rent.
The orange and red properties, in particular, have slightly more elevated chances of visiting than others, and the dark blue properties and Park Place are the least likely to be visited. The odds are skewed! It turns out that Jail is the most common space to land on in Monopoly, and when you leave Jail, you’re likely to end up on the oranges and reds. You can read about this effect in many sources (see References), and it doesn’t take proficiency in math to use this information in playing the game, but to understand why the odds are the way they are takes a little bit of background about Markov chains.
Here’s the approach I’m going to take:
- I’ll run through a simple queuing example first, using both Monte Carlo simulation and transition matrix analysis.
- Then I’ll go through a transition matrix analysis of Monopoly to determine the probability of landing on each space on the board.
- Then I’ll discuss some ways to use the results.
- We’ll end with a few additional insights.
Are you ready?
Sad Fish Bank, Revisited
A few years ago, I wrote an article covering cycle time in a semiconductor fab. I included some analysis and an interactive simulation of queueing in a bank, La Banque du Poisson Maussade.

Nobody seems very happy in this bank, for some reason. The queueing can be modeled using a Markov chain, which is just a state machine where in each state, there is a certain probability distribution of transitions to other states.
Queues are a special case of a Markov chain, where these probabilities are largely independent of state. For example, if there are \( k \) people in line waiting for a teller, at any given moment, there is some average rate \( \lambda \) that another person arrives at the end of the line (increasing the queue length by 1), and an average rate \( \mu \) that the teller finishes working with one customer, and goes on to the next (decreasing the queue length by 1).

The only state dependence in this example is that in state zero, there is nobody in line, and therefore the teller isn’t working with a customer, so the only state transition that can happen is a new customer arriving. All of the other states have transitions to an incremented or decremented queue length.
We’re going to look at a simplified version, where the queue length is limited to seven. (Prospective customers give up if they see seven people in line; nobody wants to be person number eight.)
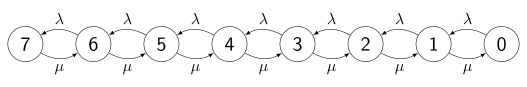
And just for numerical simplicity, let’s say that over each one-second interval, there is a 0.5% chance that a new customer arrives (\( \lambda = 1/200 \text{ s} \)), and a 1% chance (\( \mu = 1/100 \text{ s} \)) that the teller finishes working with the customer at the head of the line. And the chance that both happen in the same 1-second interval is so small (one in 20,000) that we can ignore it.
Monte Carlo Simulation
The key in Monte Carlo simulation is to make statistically-valid measurements of an infinite ensemble of possible behaviors using large numbers of pseudorandom samples from a model that approximates the system of interest. (Whoa, that’s a lot of long words! TLDR = model system with large numbers of simulated random samples.)
For example, suppose you wanted to understand what could happen in a queue of this type in general, so you decide to simulate the queue over a period of time. And then you simulate it again. And again. This is a sample of only three times — three is not infinite, but maybe you can learn something.
import numpy as np
import matplotlib.pyplot as plt
%matplotlib inline

lam = 0.005
mu = 0.01
Lmax = 7

def qsim(r, init_length, nsteps, ntrials):
    """
    Monte Carlo simulation of a queue

    - r:            RandomState
    - init_length:  initial length of the queue
    - nsteps:       number of timesteps
    - ntrials:      number of trials

    Returns a history queue length
    as a matrix of nsteps x ntrials
    """
    Lhistory = np.zeros((nsteps, ntrials))
    L = np.ones(ntrials) * init_length
    for i in range(nsteps):
        p = r.rand(ntrials)

        # +1 if 0   <= p < lam
        # -1 if lam <= p < lam+mu
        deltaL = 2 * (p < lam) - 1 * (p < (lam+mu))

        L = np.minimum(Lmax, np.maximum(0, L+deltaL))
        Lhistory[i,:] = L
    return Lhistory
Here are three different queue-length histories, starting from the same initial condition (initial queue length of 3):
r = np.random.RandomState(seed=123)
Lhistory = qsim(r, 3, nsteps=3600, ntrials=3)
fig, ax = plt.subplots()
ax.plot(Lhistory)
ax.set_xticks(np.arange(0,3601,600))
ax.set_xlabel('timesteps')
ax.set_ylabel('queue length')
ax.set_title('Queue simulation, 3 trials');

Boring.
Now let’s do something a little more interesting:
For the same one-hour interval, we’ll run 100 simulations of queues, and plot the average, minimum, 20th percentile, 80th percentile, 90th percentile, and maximum length, along with the standard deviation:
r = np.random.RandomState(seed=123)
Lhistory = qsim(r, 3, nsteps=3600, ntrials=100)
fig, ax = plt.subplots()
def qstatplot(ax, Lhistory, quantiles):
    ax.set_title('Queue simulation, %d trials' % Lhistory.shape[1])
    ax.set_xlabel('timesteps')
    ax.set_ylabel('queue length')
    ax.plot(Lhistory.mean(axis=1), label='mean')
    for q in quantiles:
        ax.plot(np.quantile(Lhistory, q, axis=1), label='%d%%' % (q*100))
    stdev = Lhistory.std(axis=1)
    ax.plot(stdev, '--', color='black', label='stdev')

qstatplot(ax, Lhistory, [0, 0.2, 0.8, 0.9, 1])
ax.set_xticks(np.arange(0,3601,600))
ax.legend(labelspacing=0, loc='upper right')
ax.grid(True, linewidth=0.5)

What if we ran 10,000 simulations?
r = np.random.RandomState(seed=123)
Lhistory = qsim(r, 3, nsteps=3600, ntrials=10000)
fig, ax = plt.subplots()
qstatplot(ax, Lhistory, [0, 0.2, 0.8, 0.9, 1])
ax.set_xticks(np.arange(0,3601,600))
ax.legend(labelspacing=0, loc='upper right')
ax.grid(True, linewidth=0.5)

What this is showing is the expected queue length decays roughly exponentially, from the initial value of 3, to a steady-state equilibrium value around 1. The quantile plots give us some measures of service level performance: after 15 minutes, 80% of the time, the queue length should be 2 or less, and 90% of the time should be 3 or less.
Of course, this is a stochastic simulation, and different runs will give slightly different results:
r = np.random.RandomState(seed=124)
Lhistory = qsim(r, 3, nsteps=3600, ntrials=10000)
fig, ax = plt.subplots()
qstatplot(ax, Lhistory, [0, 0.2, 0.8, 0.9, 1])
ax.set_xticks(np.arange(0,3601,600))
ax.legend(labelspacing=0, loc='upper right')
ax.grid(True, linewidth=0.5)

Statistics tells us that the standard deviation of the mean is approximately \( \sigma/\sqrt{N} \) where \( \sigma \) is the sample standard deviation (dashed line shown above), and \( N \) is the number of trials, so the accuracy of the mean (compared to the true mean of all possible runs of this simulation) within three standard deviations is somewhere around ±0.04 for 10,000 trials. If we wanted the results to be accurate to ±0.004, we’d have to repeat this approach for something like a million trials.
Yuck.
The Blob: Matrix Analysis to the Rescue!
Monte Carlo simulation is like a big blunt brute-force hammer: you can simulate almost anything with statistical samples, it’s just that the method has this quadratic dependency between desired accuracy and number of samples.
There are other ways to analyze Markov chains, and one of them doesn’t use sampling, but instead uses random variable probabilities directly.
In the queue example, modeled as an eight-state Markov chain, we can think of the probability distribution across the eight states as just a vector of eight numbers that add up to one. At any given time, there’s some probability of the system being in each state. If we know that the queue starts out with a length of 3, then this probability distribution is described as \( p_0 = \begin{bmatrix}0, 0, 0, 1, 0, 0, 0, 0\end{bmatrix} \) where all possible outcomes are in state 3, and the probability that the system is in any other state is zero.
The probability distribution of states in a Markov chain will change over time. You can think of it as this “stuff” that moves around between states… it diffuses… oozes… sort of like The Blob. In most real-world cases it will reach a steady state. To describe the changes over time, you just need to know the state transition matrix \( T \).
For this eight-state queue example, it’s just an 8 × 8 tridiagonal matrix:
T = (np.diag([1-lam-mu]*8)
   + np.diag([lam]*7, -1)
   + np.diag([mu]*7, 1))
T[0,0] = 1-lam
T[-1,-1] = 1-mu
T
array([[0.995, 0.01 , 0.   , 0.   , 0.   , 0.   , 0.   , 0.   ],
       [0.005, 0.985, 0.01 , 0.   , 0.   , 0.   , 0.   , 0.   ],
       [0.   , 0.005, 0.985, 0.01 , 0.   , 0.   , 0.   , 0.   ],
       [0.   , 0.   , 0.005, 0.985, 0.01 , 0.   , 0.   , 0.   ],
       [0.   , 0.   , 0.   , 0.005, 0.985, 0.01 , 0.   , 0.   ],
       [0.   , 0.   , 0.   , 0.   , 0.005, 0.985, 0.01 , 0.   ],
       [0.   , 0.   , 0.   , 0.   , 0.   , 0.005, 0.985, 0.01 ],
       [0.   , 0.   , 0.   , 0.   , 0.   , 0.   , 0.005, 0.99 ]])
Given a probability distribution \( p_k \) over the states at timestep \( k \), the probability distribution at timestep \( k+1 \) is just \( p_{k+1} = Tp_k \).
pk = np.array([0]*8)
pk[3] = 1
pk
array([0, 0, 0, 1, 0, 0, 0, 0])
np.dot(T,pk)
array([0. , 0. , 0.01 , 0.985, 0.005, 0. , 0. , 0. ])
The probabilities evolve with time; after \( k \) steps, the probability \( p_k = T^kp_0 \), and we just need to multiply the transition matrix \( T \) by itself \( k \) times.
This is pretty easy to continue numerically; here’s the first 30 steps (half a minute):
pk = np.array([0]*8)
pk[3] = 1
for k in range(31):
    print("k=%2d: [%s]" % (k, ', '.join('%.5f' % p for p in pk)))
    pk = np.dot(T,pk)
k= 0: [0.00000, 0.00000, 0.00000, 1.00000, 0.00000, 0.00000, 0.00000, 0.00000]
k= 1: [0.00000, 0.00000, 0.01000, 0.98500, 0.00500, 0.00000, 0.00000, 0.00000]
k= 2: [0.00000, 0.00010, 0.01970, 0.97032, 0.00985, 0.00003, 0.00000, 0.00000]
k= 3: [0.00000, 0.00030, 0.02911, 0.95597, 0.01455, 0.00007, 0.00000, 0.00000]
k= 4: [0.00000, 0.00058, 0.03823, 0.94192, 0.01912, 0.00015, 0.00000, 0.00000]
k= 5: [0.00001, 0.00096, 0.04708, 0.92817, 0.02354, 0.00024, 0.00000, 0.00000]
k= 6: [0.00002, 0.00141, 0.05566, 0.91472, 0.02783, 0.00035, 0.00000, 0.00000]
k= 7: [0.00003, 0.00195, 0.06398, 0.90156, 0.03199, 0.00049, 0.00000, 0.00000]
k= 8: [0.00005, 0.00256, 0.07205, 0.88867, 0.03602, 0.00064, 0.00001, 0.00000]
k= 9: [0.00008, 0.00324, 0.07987, 0.87606, 0.03993, 0.00081, 0.00001, 0.00000]
k=10: [0.00011, 0.00399, 0.08744, 0.86372, 0.04372, 0.00100, 0.00001, 0.00000]
k=11: [0.00015, 0.00481, 0.09479, 0.85164, 0.04739, 0.00120, 0.00002, 0.00000]
k=12: [0.00020, 0.00568, 0.10191, 0.83981, 0.05095, 0.00142, 0.00002, 0.00000]
k=13: [0.00025, 0.00662, 0.10881, 0.82823, 0.05440, 0.00165, 0.00003, 0.00000]
k=14: [0.00032, 0.00761, 0.11549, 0.81690, 0.05774, 0.00190, 0.00004, 0.00000]
k=15: [0.00039, 0.00865, 0.12196, 0.80580, 0.06098, 0.00216, 0.00005, 0.00000]
k=16: [0.00048, 0.00974, 0.12824, 0.79493, 0.06412, 0.00244, 0.00006, 0.00000]
k=17: [0.00057, 0.01088, 0.13431, 0.78429, 0.06716, 0.00272, 0.00007, 0.00000]
k=18: [0.00068, 0.01206, 0.14019, 0.77387, 0.07010, 0.00302, 0.00008, 0.00000]
k=19: [0.00079, 0.01329, 0.14589, 0.76366, 0.07294, 0.00332, 0.00010, 0.00000]
k=20: [0.00092, 0.01455, 0.15140, 0.75367, 0.07570, 0.00364, 0.00011, 0.00000]
k=21: [0.00106, 0.01585, 0.15674, 0.74388, 0.07837, 0.00396, 0.00013, 0.00000]
k=22: [0.00122, 0.01719, 0.16191, 0.73429, 0.08095, 0.00430, 0.00015, 0.00000]
k=23: [0.00138, 0.01855, 0.16691, 0.72489, 0.08345, 0.00464, 0.00016, 0.00000]
k=24: [0.00156, 0.01995, 0.17175, 0.71569, 0.08587, 0.00499, 0.00019, 0.00001]
k=25: [0.00175, 0.02138, 0.17643, 0.70667, 0.08821, 0.00534, 0.00021, 0.00001]
k=26: [0.00196, 0.02283, 0.18096, 0.69783, 0.09048, 0.00571, 0.00023, 0.00001]
k=27: [0.00218, 0.02431, 0.18533, 0.68918, 0.09267, 0.00608, 0.00026, 0.00001]
k=28: [0.00241, 0.02581, 0.18957, 0.68069, 0.09478, 0.00645, 0.00028, 0.00001]
k=29: [0.00266, 0.02733, 0.19366, 0.67238, 0.09683, 0.00683, 0.00031, 0.00001]
k=30: [0.00292, 0.02887, 0.19761, 0.66423, 0.09881, 0.00722, 0.00034, 0.00001]
Well, we might as well graph it:
colors = plt.rcParams['axes.prop_cycle'].by_key()['color']
def enumerate_markercolors(markers, colors, n):
    nmarkers = len(markers)
    ncolors = len(colors)
    for i in range(n):
        yield (i, markers[i%nmarkers], colors[i%ncolors])

p0 = np.array([0]*8)
p0[3] = 1

Npoints = 2400
phistory = np.zeros((Npoints, 8))
t = np.arange(Npoints)
pk = p0
for k in range(Npoints):
    phistory[k,:] = pk
    pk = np.dot(T,pk)

fig,ax = plt.subplots(figsize=(10,6))
legend_handles = []
for i, marker, color in enumerate_markercolors('.o*<>v^+', colors, 8):
    hline,    = ax.plot(t,phistory[:,i], color=color)
    hmarkers, = ax.plot(t[0::300], phistory[0::300,i],
            marker=marker, linestyle='none', color=color)
    legend_handles.append((hline, hmarkers))
ax.legend(handles=legend_handles,
          labels=['%d' % i for i in range(8)],
          title='Queue length', labelspacing=0)
ax.grid(True, axis='y', linewidth=0.5)
ax.set_ylim(0,1)
ax.set_yticks(np.arange(0,1.001,0.1))
ax.set_xlim(0,Npoints)
ax.set_xticks(np.arange(0,Npoints+1,300))
ax.set_ylabel('Probability')
ax.set_xlabel('Time (steps = seconds)')
ax.set_title('Evolution of queue length probabilities over time,\nstarting with length 3; '+
             '$\\lambda=0.005, \\mu=0.1$');

Note from the numerical data and the graph:
- at step \( k=0 \), the queue length distribution is known at length 3 with probability 1.
- at step \( k=1 \), the probability is relatively high (98.5%) that the queue length remains at 3, but there’s a 1% chance the queue length decreased to 2, and a 0.5% chance it increased to 4.
- as \( k \) increases, this probability distribution oozes outward, and after three minutes (\( k=180 \)) the most likely queue lengths are 2 and 3
- after ten minutes (\( k=600 \)) there is more than a 40% chance the queue length is zero
- after this time, the probabilities of lengths 0 and 1 increase slightly, whereas lengths two or more decrease in probability.
- after thirty minutes (\( k=1800 \)) the distribution has almost stabilized.
The long-term probability distribution among the states is nearly an exponential distribution; after 2400 steps (forty minutes) it looks like this:
pk
array([0.49990137, 0.25034997, 0.12569621, 0.06332903, 0.03203202,
       0.01625573, 0.00825743, 0.00417825])
Once you realize that a matrix is involved, if you have an understanding of matrix theory, some insight will show that the resulting long-term distribution is equal to the eigenvector with the largest eigenvalue. It turns out that for a specific type of Markov chain, called an “ergodic” Markov chain, where it is possible to get from any state to any other state with some nonzero probability, there is always a single eigenvalue of 1 (all other eigenvalues smaller) and its associated right eigenvector gives the steady-state probability, known as the stationary distribution. (Technicality: use the right eigenvector if the transition matrix contains one column for each source state and multiplies on the left: \( p_\infty = Tp_\infty \); use the left eigenvector if the transition matrix is transposed and contains one row for each source state and multiplies on the right: \( p_\infty = p_\infty T \).)
This is because we can write the probability distribution among states at step \( k \) in terms of the transition matrix’s eigendecomposition \( T = Q\Lambda Q^{-1} \) where \( \Lambda \) is the diagonal matrix of eigenvalues and \( Q \) is a matrix of eigenvectors:
$$\begin{aligned} p_k &= T^kp_0 \\ &= (Q\Lambda Q^{-1})^kp_0 \\ &= Q\Lambda^k Q^{-1}p_0 \end{aligned}$$
The terms of \( \Lambda^k \) get smaller and smaller over time, except for the eigenvalue 1, which remains.
Step-by-step Guide to Calculating the Stationary Distribution of Markov Chains
In case you don’t care about the math other than getting the answer, here’s a short guide:
- Define the problem. In this case it’s the queue behavior: 0 – 7 people in line, one timestep per second, probability \( \lambda \) for the line length to increase by one, probability \( \mu \) for the line length to decrease by one, otherwise stay the same.
- Define the states. In this case it’s the number of people in line. Make sure the probabilities are dependent only on the state value, otherwise it’s not a Markov chain.
- Calculate the state transition matrix \( T \). For each pair of states \( (S_i, S_j) \), compute the entry \( T_{j,i} \) (\( i \)th column, \( j \)th row) as the probability of a transition \( S_i \to S_j \). The entries of each column should add up to 1.
- Find the stationary distribution. There are at least three different ways of doing this:
- Brute force timestep evolution (power iteration): Start with an initial probability \( p_0 \) and keep multiplying \( p_k = Tp_{k-1} \), until you reach steady-state and the values don’t change significantly. This works well for transition matrices that don’t have long timescales; multiplication of a square matrix and a vector of size \( N \) takes \( N^2 \) multiplications and additions.
- Brute force eigenvalue/eigenvector computation: Use a numerical function to compute the eigenvectors and eigenvalues (for example
numpy.linalg.eig), and find the eigenvector that corresponds to the eigenvalue of 1. Then normalize this eigenvector so its entries sum to 1. This works well for long timescales if the matrix sizes aren’t large; runtime is \( O(N^3) \). (See LAPACK documentation.) This method also lets you find the second largest eigenvalue, which determines the timescale of a Markov chain to approach steady-state. - Compute the specific eigenvector: Use a numerical function to find the eigenvector for the eigenvalue 1. (For example
scipy.linalg.null_spaceto find the null space of \( T - \lambda I \) for \( \lambda=1 \)) Then normalize this eigenvector so its entries sum to 1. However this method doesn’t seem to have any time advantages over brute force eigenvector computation, unless the transition matrix has a specific structure.
I will also add two additional notes; we’ll talk more about both later on.
- Take reasonable effort to check your work.
- Interpret the results to suit your needs.
We’ll use each of the three methods of finding the stationary distribution for our eight-state queue example:
A. Brute force timestep evolution (power iteration)
def markov_power_iteration(T, kmax = 100000, tolerance=None):
    N = T.shape[0]
    if tolerance is None:
        tolerance = np.finfo(float).eps
    assert T.shape[1] == N
    pk = np.ones(N) / N
    for k in range(kmax):
        pknext = np.dot(T,pk)
        delta = pk - pknext
        if (np.abs(delta) < tolerance).all():
            break
        pk = pknext
    return pk, k

markov_power_iteration(T)
(array([0.50196078, 0.25098039, 0.1254902 , 0.0627451 , 0.03137255,
        0.01568627, 0.00784314, 0.00392157]),
 15128)
Here it took just over fifteen thousand iterations of multiplying \( p_{k} = Tp_{k-1} \) to reach full machine precision for the default float data type.
B. Brute force eigenvalue/eigenvector computation
def find_markov_eigenvector(T):
    # Find eigenvectors
    eigval, V = np.linalg.eig(T)
    ii = np.abs(eigval - 1.0) < 1e-12

    # Find the index of eigenvalue 1, and test assertions
    # 1. There should be only one such eigenvalue
    assert sum(ii) == 1
    # 2. All other eigenvalues are smaller
    assert (np.abs(eigval[~ii]) < 1).all()
    i = np.nonzero(ii)[0][0]
    Vp = V[:,i]
    # 3. All eigenvector values are real
    assert (Vp.imag == 0).all()
    Vp = Vp.real
    return Vp / sum(Vp)

find_markov_eigenvector(T)
array([0.50196078, 0.25098039, 0.1254902 , 0.0627451 , 0.03137255,
       0.01568627, 0.00784314, 0.00392157])
C. Specific eigenvector computation
import scipy.linalg

def find_markov_eigenvector_1(T):
    """finds the eigenvector corresponding to eigenvalue 1"""
    N = T.shape[0]
    assert T.shape[1] == N
    v = scipy.linalg.null_space(T - np.eye(N))
    assert v.shape[1] == 1
    return v[:,0] / sum(v)

find_markov_eigenvector_1(T)
array([0.50196078, 0.25098039, 0.1254902 , 0.0627451 , 0.03137255,
       0.01568627, 0.00784314, 0.00392157])
Which method to choose?
Which method? Again, it depends on the number of states and the rate at which transients reach steady state. For large matrices that decay fast, you’re better off with power iteration; otherwise a brute-force eigenvector calculation is probably best.
For all three of these cases, the advantage of an exact answer (within numerical precision) is that we don’t have to mess around with the uncertainty of Monte Carlo simulation.
The eigenvalues themselves are useful for understanding how transients decay to steady-state. This matrix’s eigenvalues are fairly close to 1:
eigval, V = np.linalg.eig(T)
eigval
array([0.97193437, 0.975     , 0.97958804, 0.985     , 0.99041196,
       1.        , 0.99806563, 0.995     ])
The second-largest eigenvalue is roughly 0.99807, which takes quite a while to die out:
- after 600 steps its contribution is \( 0.99807^{600} \approx 0.3138 \)
- after 1200 steps: \( 0.99807^{1200} \approx 0.0985 \)
- after 2400 steps: \( 0.99807^{2400} \approx 0.0097 \)
This gives us an idea of how long it takes to approximate a steady-state probability distribution, on the order of 2400 steps to reach one part in one hundred.
Monopoly
OK, so how do we apply these steps to Monopoly?
Define the Problem
We want to know the steady-state probability of a player’s token landing on each of the board spaces of Monopoly during a turn.
All we care about is the rules of movement; we don’t care about any of the monetary transactions — purchasing properties or rents or houses or mortgages — or who wins.
The tokens move independently around the board based on the results of rolling of a pair of dice; we’ll go over the rules in a moment.
Define the States
OK, so what does the state machine look like for Monopoly? How many states are there?
Darrow’s patent, granted on the last day of 1935, shows the 40 spaces of the board, as well as the six original tokens (thimble, cannon, flat iron, hat, shoe, and battleship):

So there must be 40 states, right?
Wrong.
Here are the mechanics of movement in Monopoly for each roll (throw) of the dice. (Thankfully, the movement of each player is independent from the others.)
- Roll the dice and move your token that many spaces clockwise around the board.
- If you land on the “Go to Jail” space, go to Jail. (Do not pass Go, do not collect \$200.)
- If you land on one of the three Community Chest spaces, take the yellow card from the top of Community Chest pile and do what it says. Two of these cards (“Go to Jail” and “Advance to Go”) move the token elsewhere, the other fourteen do not.

-
If you land on one of the three Chance spaces, take the orange card from the top of the Chance pile and do what it says. Ten of these cards move the player’s token, and the other six do not.

-
Otherwise, your roll ends on the spot where you landed.
Each player has up to three dice rolls per turn.
If you roll doubles (same number on each of the two dice) then you get another roll. If you roll doubles again, you get a third roll. If you roll doubles three times, you do not move your token but instead go directly to Jail, and that is the end of your turn. Going to Jail always ends your turn: if you land on “Go to Jail” or draw a card that says “Go to Jail”, then it’s the next player’s turn, even if you rolled doubles.
If you’re in Jail at the beginning of your turn, you have three turns to get out, either by paying \$50, using a “Get Out of Jail Free” card you drew from the Community Chest or Chance piles, or rolling the dice and getting doubles, in which case the roll determines how many spaces you move. On the third turn, if you roll the dice to get out, the roll determines how many spaces you move and whether you have to pay or not:
- if you get doubles, you do not have to pay, but you do not get another turn
- if you don’t get doubles, you must pay \$50 or use a “Get Out of Jail Free” card

That’s it — those are all the movement rules.
Token movement in the game is almost completely dependent on dice rolls and the Chance and Community Chest cards, with the only player-dependent movement being the choice of how to get out of Jail. For this analysis, I will make the following assumptions, taking that choice out of the equation:
- the player always rolls dice to try to get out of Jail,
- the player never uses a Get Out of Jail Free card
- the Chance and Community Chest cards are memoryless, drawn at random from each set of 16 cards (in reality, the game state and likelihood of drawing a card depends on what cards were drawn previously)
This leaves the player’s move state at the end of each turn as a function of two things:
- the space on the board where the token ends up
- the history of doubles rolls: either the number of doubles if not in Jail, or the number of non-doubles if in Jail.
If a player is not in Jail, there are 39 spaces, including Just Visiting which is in the same “square” as Jail, but distinct from it, and not including the “Go to Jail” space, which is never occupied at the end of a turn, because the player is moved to Jail. The player’s turn can end on any of these, on the first, second, or third roll.
There are three turns which may end in Jail. The turn that you end up there, you cannot get out. The first and second turns when you are in jail, you may get out if you roll doubles. The third turn constitutes a roll (without any opportunities to take another roll) to send the player elsewhere, that ends on a variety of spaces.
So the total number of states needed is 39 × 3 + 3 = 120.
We can number these as follows:
- 0 to 39: end of turn (no next turn from doubles)
- 0 = Go
- 1 = Mediterranean Ave.
- 2 = Community Chest
- 3 = Baltic Ave.
- 4 = Income Tax
- 5 = Reading Railroad
- 6 = Oriental Ave.
- 7 = Chance
- 8 = Vermont Ave.
- 9 = Connecticut Ave.
- 10 = Just Visiting
- 11 = St. Charles Place
… - 28 = Water Works
- 29 = Marvin Gardens
- 30 = Jail, arriving (even though the location on the board is on the other corner)
- 31 = Pacific Ave.
- 32 = North Carolina Ave.
… - 37 = Park Place
- 38 = Luxury Tax
- 39 = Boardwalk
- 40 to 69, and 71 to 79: doubles rolled once
- 70: Jail, first turn after arriving
- 80 to 109, and 111 to 119: doubles rolled twice
- 110: Jail, second turn after arriving

So for example, a player could be on Pacific Avenue (state 31 / 71 / 111) and roll a 7 = ⚀⚅ (not doubles), to arrive at state 38 (Luxury Tax, no next turn from doubles). Then on the player’s next turn, roll a 2 = ⚀⚀, and land on state 40 (Go, first doubles rolled).
Calculate the State Transition Matrix
To calculate the state transition matrix \( T \) we have a bunch of tedious work to do, but it’s not overly complicated.
For example, the possibilities from state 40 (Go, first doubles rolled) are as follows:

- roll 1+1: Community Chest: (probability 1/36)
- state 82 (Community Chest, second doubles), probability 1/36 × 14/16
- state 30 (Jail, first turn), probability 1/36 × 1/16
- state 80 (Go, second doubles), probability 1/36 × 1/16
- roll 3: state 3 (Baltic Ave., no next turn from doubles), probability 2/36
- roll 1+3 or 3+1: state 4 (Income Tax, no next turn from doubles), probability 2/36
- roll 2+2: state 84 (Income Tax, second doubles), probability 1/36
- roll 5: state 5 (Reading Railroad, no next turn from doubles), probability 4/36
- roll 1+5, 2+4, 4+2, or 5+1: state 6 (Oriental Ave., no next turn from doubles), probability 4/36
- roll 3+3: state 86 (Oriental Ave., second doubles), probability 1/36
- roll 7: Chance: (probability 6/36)
- state 7 (Chance card without movement, no next turn from doubles), probability 6/36 × 6/16
- state 4 (“Go Back 3 Spaces” to Income Tax, no next turn from doubles), probability 6/36 × 1/16
- state 11 (“Advance to St. Charles Place”, no next turn from doubles), probability 6/36 × 1/16
- state 12 (“Advance to Nearest Utililty” to Electric Company, no next turn from doubles), probability 6/36 × 1/16
- state 15 (two cards: “Advance token to the nearest Railroad” to Pennsylvania Railroad, no next turn from doubles), probability 6/36 × 2/16
- state 24 (“Advance to Illinois Ave.”, no next turn from doubles), probability 6/36 × 1/16
- state 30 (“Go Directly to Jail”, first turn), probability 6/36 × 1/16
- state 39 (“Advance Token to Board Walk” to Boardwalk, no next turn from doubles), probability 6/36 × 1/16
- state 0 (“Advance to Go”, no next turn from doubles), probability 6/36 × 1/16
- state 5 (“Take a Ride on the Reading” to Reading Railroad, no next turn from doubles), probability 6/36 × 1/16
- roll 2+6, 3+5, 5+3, 6+2: state 8 (Vermont Ave, no next turn from doubles), probability 4/36
- roll 4+4: state 88 (Vermont Ave, second doubles), probability 1/36
- roll 9: state 9 (Connecticut Ave, no next turn from doubles), probability 4/36
- roll 4+6, 6+4: state 10 (Just Visiting, no next turn from doubles), probability 2/36
- roll 5+5: state 90 (Just Visiting, second doubles), probability 1/36
- roll 11: state 11 (St. Charles Place, no next turn from doubles), probability 2/36
- roll 6+6: state 92 (Electric Company, second doubles), probability 1/36
Repeat this analysis for all 120 states, and you get a 120 × 120 transition matrix \( T \).
It’s difficult to visualize the content of this transition matrix, so let’s go through some of the cases, including the one I just mentioned. (from Go, with first doubles already rolled)
I’m using the monopoly module from my repository, so feel free to try this yourself.
import monopoly

mchain = monopoly.MonopolyChain()

for transition in mchain.transitions_from(monopoly.Space.GO, ndoubles=1):
    print(transition.describe())
 82: #2 Community Chest (S)   p=0.875/36
 30: #0 Jail                  p=0.0625/36
 80: #2 Go                    p=0.0625/36
  3: #0 Baltic Avenue         p=2/36
 84: #2 Income Tax            p=1/36
  4: #0 Income Tax            p=2/36
  5: #0 Reading Railroad      p=4/36
 86: #2 Oriental Avenue       p=1/36
  6: #0 Oriental Avenue       p=4/36
  7: #0 Chance (S)            p=2.25/36
 24: #0 Illinois Avenue       p=0.375/36
 15: #0 Pennsylvania Railroad p=0.375/36
 15: #0 Pennsylvania Railroad p=0.375/36
  4: #0 Income Tax            p=0.375/36
 12: #0 Electric Company      p=0.375/36
  0: #0 Go                    p=0.375/36
 11: #0 St. Charles Place     p=0.375/36
 39: #0 Boardwalk             p=0.375/36
  5: #0 Reading Railroad      p=0.375/36
 30: #0 Jail                  p=0.375/36
 88: #2 Vermont Avenue        p=1/36
  8: #0 Vermont Avenue        p=4/36
  9: #0 Connecticut Avenue    p=4/36
 90: #2 Just Visiting         p=1/36
 10: #0 Just Visiting         p=2/36
 11: #0 St. Charles Place     p=2/36
 92: #2 Electric Company      p=1/36
Add these up for the content of the full transition matrix, and repeat for all three doubles possibilities, and we can summarize the content of three columns of the matrix representing transitions from Go — shown below as a table measuring probability in “pipchances” (1/36ths):
def get_formatted_transition_table(mchain, space):
    T = mchain.get_space_transition_table(space, concise_format=True)
    # displays the probability transitions from designated space to other spaces
    # with the designated number of doubles
    # in "pipchances" (1/36ths)
    return T.set_table_styles([dict(selector='th.row_heading', props=[('class', 'ha-left')])])

get_formatted_transition_table(mchain, monopoly.Space.GO)
| from_doubles | 0 | 1 | 2 | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| to_doubles | # | 0 | 1 | 2 | 0 | 1 | 2 | 0 | 1 | 2 |
| Go | 0 | 0.375 | 0.0625 | 0.375 | 0.0625 | 0.375 | ||||
| Community Chest (S) | 2 | 0.875 | 0.875 | |||||||
| Baltic Avenue | 3 | 2 | 2 | 2 | ||||||
| Income Tax | 4 | 2.375 | 1 | 2.375 | 1 | 2.375 | ||||
| Reading Railroad | 5 | 4.375 | 4.375 | 4.375 | ||||||
| Oriental Avenue | 6 | 4 | 1 | 4 | 1 | 4 | ||||
| Chance (S) | 7 | 2.25 | 2.25 | 2.25 | ||||||
| Vermont Avenue | 8 | 4 | 1 | 4 | 1 | 4 | ||||
| Connecticut Avenue | 9 | 4 | 4 | 4 | ||||||
| Just Visiting | 10 | 2 | 1 | 2 | 1 | 2 | ||||
| St. Charles Place | 11 | 2.375 | 2.375 | 2.375 | ||||||
| Electric Company | 12 | 0.375 | 1 | 0.375 | 1 | 0.375 | ||||
| Pennsylvania Railroad | 15 | 0.75 | 0.75 | 0.75 | ||||||
| Illinois Avenue | 24 | 0.375 | 0.375 | 0.375 | ||||||
| Jail | 30 | 0.4375 | 0.4375 | 6.375 | ||||||
| Boardwalk | 39 | 0.375 | 0.375 | 0.375 | ||||||
The three columns of this table under the “0” in the top row represent the content of the transition matrix for the Go space with the first roll of a turn (no doubles so far); the next three columns for the second roll of a turn, and the last three columns for the third roll of a turn.
There are only a few possibilities in doubles transitions:
- 0 → 0 (on first roll of turn, player does not roll doubles, and ends turn)
- 0 → 1 (on first roll of turn, player rolls doubles, and keeps going)
- 1 → 0 (on second roll of turn, player does not roll doubles, and ends turn)
- 1 → 2 (on second roll of turn, player rolls doubles, and keeps going)
- 2 → 0 (on third roll of turn, player either does not roll doubles, and ends turn, or rolls doubles and goes to Jail)
The remaining columns (0 → 2, 1 → 1, 2 → 1, 2 → 2) are all zero-probability.
The “1” entry for Just Visiting in the 1 → 2 column represents \( T[90, 40] = 1/36 \approx 0.027778 \): the row index is 90 (= 10 for Just Visiting, plus 2 × 40 for two doubles thrown entering the third roll of a turn) and the column index is 40 (= 0 for Go, plus 40 for the first double thrown entering the second roll of a turn). In this case the player has just rolled a double-five ⚄⚄.
Similarly, the 4.375 on the leftmost column for Reading Railroad represents \( T[5,0] = 4.375/36 \approx 0.121556 \): the row index is 5 for Reading Railroad and the column index is 0 for Go (first roll of a turn, no next turn from doubles). In this case the player has either:
- just rolled five (4/36 chance: ⚀⚃, ⚁⚂, ⚂⚁, or ⚃⚀)
- just landed on Chance by rolling seven (6/36 chance) and drawn the “Take a Ride on the Reading” card (1/16 chance), for a net chance of 6/36 × 1/16 = 0.375/36
The transitions from North Carolina Ave. look to be the most complex, since a player can land on Chance either with a doubles or non-doubles roll, and the “Go Back 3 Spaces” Chance card puts them onto the east-side Community Chest, which can then send the player to Go or Jail:
for transition in mchain.transitions_from(monopoly.Space.NORTH_CAROLINA, ndoubles=0):
    print(transition.describe())
 74: #1 Pennsylvania Avenue   p=1/36
 35: #0 Short Line            p=2/36
 76: #1 Chance (E)            p=0.375/36
 64: #1 Illinois Avenue       p=0.0625/36
 45: #1 Reading Railroad      p=0.0625/36
 45: #1 Reading Railroad      p=0.0625/36
 73: #1 Community Chest (E)   p=0.0546875/36
 30: #0 Jail                  p=0.00390625/36
 40: #1 Go                    p=0.00390625/36
 52: #1 Electric Company      p=0.0625/36
 40: #1 Go                    p=0.0625/36
 51: #1 St. Charles Place     p=0.0625/36
 79: #1 Boardwalk             p=0.0625/36
 45: #1 Reading Railroad      p=0.0625/36
 30: #0 Jail                  p=0.0625/36
 36: #0 Chance (E)            p=0.75/36
 24: #0 Illinois Avenue       p=0.125/36
  5: #0 Reading Railroad      p=0.125/36
  5: #0 Reading Railroad      p=0.125/36
 33: #0 Community Chest (E)   p=0.109375/36
 30: #0 Jail                  p=0.0078125/36
  0: #0 Go                    p=0.0078125/36
 12: #0 Electric Company      p=0.125/36
  0: #0 Go                    p=0.125/36
 11: #0 St. Charles Place     p=0.125/36
 39: #0 Boardwalk             p=0.125/36
  5: #0 Reading Railroad      p=0.125/36
 30: #0 Jail                  p=0.125/36
 37: #0 Park Place            p=4/36
 78: #1 Luxury Tax            p=1/36
 38: #0 Luxury Tax            p=4/36
 39: #0 Boardwalk             p=6/36
 40: #1 Go                    p=1/36
  0: #0 Go                    p=4/36
  1: #0 Mediterranean Avenue  p=4/36
 42: #1 Community Chest (S)   p=0.875/36
 30: #0 Jail                  p=0.0625/36
 40: #1 Go                    p=0.0625/36
  2: #0 Community Chest (S)   p=1.75/36
 30: #0 Jail                  p=0.125/36
  0: #0 Go                    p=0.125/36
  3: #0 Baltic Avenue         p=2/36
 44: #1 Income Tax            p=1/36
get_formatted_transition_table(mchain, monopoly.Space.NORTH_CAROLINA)
| from_doubles | 0 | 1 | 2 | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| to_doubles | # | 0 | 1 | 2 | 0 | 1 | 2 | 0 | 1 | 2 |
| Go | 0 | 4.25781 | 1.12891 | 4.25781 | 1.12891 | 4.25781 | ||||
| Mediterranean Avenue | 1 | 4 | 4 | 4 | ||||||
| Community Chest (S) | 2 | 1.75 | 0.875 | 1.75 | 0.875 | 1.75 | ||||
| Baltic Avenue | 3 | 2 | 2 | 2 | ||||||
| Income Tax | 4 | 1 | 1 | |||||||
| Reading Railroad | 5 | 0.375 | 0.1875 | 0.375 | 0.1875 | 0.375 | ||||
| St. Charles Place | 11 | 0.125 | 0.0625 | 0.125 | 0.0625 | 0.125 | ||||
| Electric Company | 12 | 0.125 | 0.0625 | 0.125 | 0.0625 | 0.125 | ||||
| Illinois Avenue | 24 | 0.125 | 0.0625 | 0.125 | 0.0625 | 0.125 | ||||
| Jail | 30 | 0.386719 | 0.386719 | 6.25781 | ||||||
| Community Chest (E) | 33 | 0.109375 | 0.0546875 | 0.109375 | 0.0546875 | 0.109375 | ||||
| Pennsylvania Avenue | 34 | 1 | 1 | |||||||
| Short Line | 35 | 2 | 2 | 2 | ||||||
| Chance (E) | 36 | 0.75 | 0.375 | 0.75 | 0.375 | 0.75 | ||||
| Park Place | 37 | 4 | 4 | 4 | ||||||
| Luxury Tax | 38 | 4 | 1 | 4 | 1 | 4 | ||||
| Boardwalk | 39 | 6.125 | 0.0625 | 6.125 | 0.0625 | 6.125 | ||||
Going to Jail complicates the structure of the transition matrix, since it always ends a player’s turn, regardless of whether doubles were rolled. The probability of going to Jail on the third roll is at most 6 pipchances (6/36) higher than on the first two rolls, because that’s the chance of rolling doubles on the third roll, which sends a player to Jail. (It’s at most 5 pipchances higher if the player can end up in jail by rolling doubles on either of the first two rolls and landing on Go to Jail, and slightly less if the player can reach jail by rolling doubles on either of the first two rolls and drawing a Go to Jail card from Chance or Community Chest. This is because the third roll removes these possibilities.)
get_formatted_transition_table(mchain, monopoly.Space.CHANCE_N)
| from_doubles | 0 | 1 | 2 | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| to_doubles | # | 0 | 1 | 2 | 0 | 1 | 2 | 0 | 1 | 2 |
| Go | 0 | 0.125 | 0.125 | 0.125 | ||||||
| Illinois Avenue | 24 | 1 | 1 | |||||||
| B. & O. Railroad | 25 | 2 | 2 | 2 | ||||||
| Atlantic Avenue | 26 | 2 | 1 | 2 | 1 | 2 | ||||
| Ventnor Avenue | 27 | 4 | 4 | 4 | ||||||
| Water Works | 28 | 4 | 1 | 4 | 1 | 4 | ||||
| Marvin Gardens | 29 | 6 | 6 | 6 | ||||||
| Jail | 30 | 5.125 | 5.125 | 10.125 | ||||||
| Pacific Avenue | 31 | 4 | 4 | 4 | ||||||
| North Carolina Avenue | 32 | 2 | 1 | 2 | 1 | 2 | ||||
| Community Chest (E) | 33 | 1.75 | 1.75 | 1.75 | ||||||
| Pennsylvania Avenue | 34 | 1 | 1 | |||||||
And the probability of landing on different spaces from Jail is complicated. On the first two turns there is a 30/36 chance of staying there (not rolling doubles); the only way of leaving is to roll doubles, with a 1/36 chance of rolling double-six ⚅⚅ to land on Chance on the north side of the board. On the third turn, the distribution is more normal but the player does not get to roll again.
get_formatted_transition_table(mchain, monopoly.Space.JAIL)
| from_doubles | 0 | 1 | 2 | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| to_doubles | # | 0 | 1 | 2 | 0 | 1 | 2 | 0 | 1 | 2 |
| Go | 0 | 0.0625 | 0.0625 | 0.4375 | ||||||
| Reading Railroad | 5 | 0.0625 | 0.0625 | 0.0625 | ||||||
| St. Charles Place | 11 | 0.0625 | 0.0625 | 0.0625 | ||||||
| Electric Company | 12 | 1 | 1 | 1 | ||||||
| States Avenue | 13 | 2 | ||||||||
| Virginia Avenue | 14 | 1 | 1 | 3 | ||||||
| Pennsylvania Railroad | 15 | 4 | ||||||||
| St. James Place | 16 | 1 | 1 | 5 | ||||||
| Community Chest (W) | 17 | 5.25 | ||||||||
| Tennessee Avenue | 18 | 1 | 1 | 5 | ||||||
| New York Avenue | 19 | 0.0625 | 0.0625 | 4.0625 | ||||||
| Free Parking | 20 | 1 | 1 | 3 | ||||||
| Kentucky Avenue | 21 | 2 | ||||||||
| Chance (N) | 22 | 0.375 | 0.375 | 0.375 | ||||||
| Illinois Avenue | 24 | 0.0625 | 0.0625 | 0.0625 | ||||||
| B. & O. Railroad | 25 | 0.125 | 0.125 | 0.125 | ||||||
| Water Works | 28 | 0.0625 | 0.0625 | 0.0625 | ||||||
| Jail | 30 | 0.0625 | 30 | 0.0625 | 30 | 0.4375 | ||||
| Boardwalk | 39 | 0.0625 | 0.0625 | 0.0625 | ||||||
Stationary distributions in Monopoly
All this is prologue, though, to the question we’re trying to answer: what is the frequency of landing on the different spaces?
Once we have the 120 × 120 transition matrix \( T \), we can compute the eigenvector for eigenvalue 1, and normalize it so that the resulting vector \( \bar{\mathbf{v}} \) has a total probability of 1. This represents the stationary distribution, which is the steady-state probability of each state in the Markov chain.
We do have to be careful to specify exactly which question we’re trying to answer, though. There are actually three ways to define the probability of landing on different spaces:
- at the end of each roll
- at the end of each turn
- during each turn
The normalized eigenvector \( \bar{\mathbf{v}} \) calculated from the transition matrix \( T \) computes the stationary distribution of all 120 states at the end of each roll, and it’s the series of 120 numbers given in columns (0, 1, 2) in the table below:
import pandas as pd

ftable = mchain.get_frequency_table()
def fancy_freq_table_style(df):
    percent_columns = df.select_dtypes(include=['float']).columns
    return df.style.format(
        formatter="{:.4%}",
        subset=percent_columns
    ).set_td_classes(
        pd.DataFrame(
            {col: "ha-right" if col != "space" else ""
             for col in df.columns},
            index=df.index
        )
    )

p_total = ftable.sum().to_dict()
p_total.update(space='', rank='')
fancy_freq_table_style(ftable).concat(
    fancy_freq_table_style(pd.DataFrame(p_total, index=['Total']))
)
| space | 0 | 1 | 2 | end of roll | end of turn | during turn | rank | |
|---|---|---|---|---|---|---|---|---|
| 0 | Go | 2.4961% | 0.3665% | 0.0557% | 2.9183% | 2.9102% | 3.4024% | 3 |
| 1 | Mediterranean Avenue | 1.6304% | 0.3199% | 0.0597% | 2.0100% | 1.9009% | 2.3435% | 36 |
| 2 | Community Chest (S) | 1.5241% | 0.2219% | 0.0315% | 1.7775% | 1.7769% | 2.0724% | 37 |
| 3 | Baltic Avenue | 1.6721% | 0.3093% | 0.0583% | 2.0398% | 1.9495% | 2.3782% | 35 |
| 4 | Income Tax | 1.8354% | 0.3154% | 0.0459% | 2.1966% | 2.1399% | 2.5610% | 27 |
| 5 | Reading Railroad | 2.3347% | 0.3977% | 0.0725% | 2.8050% | 2.7220% | 3.2703% | 8 |
| 6 | Oriental Avenue | 1.8043% | 0.2872% | 0.0431% | 2.1346% | 2.1036% | 2.4887% | 32 |
| 7 | Chance (S) | 0.6777% | 0.1168% | 0.0219% | 0.8164% | 0.7901% | 0.9518% | 40 |
| 8 | Vermont Avenue | 1.8662% | 0.2807% | 0.0434% | 2.1903% | 2.1758% | 2.5537% | 28 |
| 9 | Connecticut Avenue | 1.8413% | 0.2779% | 0.0519% | 2.1712% | 2.1468% | 2.5314% | 30 |
| 10 | Just Visiting | 1.7807% | 0.3135% | 0.0480% | 2.1422% | 2.0761% | 2.4976% | 31 |
| 11 | St. Charles Place | 2.1547% | 0.3447% | 0.0602% | 2.5596% | 2.5122% | 2.9842% | 15 |
| 12 | Electric Company | 2.2065% | 0.3528% | 0.0562% | 2.6155% | 2.5726% | 3.0494% | 12 |
| 13 | States Avenue | 1.8405% | 0.2864% | 0.0491% | 2.1760% | 2.1459% | 2.5370% | 29 |
| 14 | Virginia Avenue | 2.0700% | 0.3060% | 0.0492% | 2.4253% | 2.4134% | 2.8276% | 22 |
| 15 | Pennsylvania Railroad | 2.2500% | 0.3312% | 0.0554% | 2.6366% | 2.6232% | 3.0740% | 11 |
| 16 | St. James Place | 2.3062% | 0.3212% | 0.0515% | 2.6789% | 2.6888% | 3.1233% | 9 |
| 17 | Community Chest (W) | 1.9827% | 0.2698% | 0.0426% | 2.2951% | 2.3116% | 2.6759% | 24 |
| 18 | Tennessee Avenue | 2.4337% | 0.3343% | 0.0517% | 2.8197% | 2.8374% | 3.2875% | 6 |
| 19 | New York Avenue | 2.4415% | 0.3215% | 0.0486% | 2.8116% | 2.8465% | 3.2780% | 7 |
| 20 | Free Parking | 2.4200% | 0.3518% | 0.0530% | 2.8248% | 2.8215% | 3.2934% | 5 |
| 21 | Kentucky Avenue | 2.2158% | 0.3475% | 0.0509% | 2.6142% | 2.5834% | 3.0479% | 13 |
| 22 | Chance (N) | 0.8867% | 0.1377% | 0.0206% | 1.0450% | 1.0337% | 1.2183% | 38 |
| 23 | Indiana Avenue | 2.1566% | 0.3579% | 0.0528% | 2.5673% | 2.5143% | 2.9932% | 14 |
| 24 | Illinois Avenue | 2.5314% | 0.4039% | 0.0601% | 2.9955% | 2.9514% | 3.4924% | 2 |
| 25 | B. & O. Railroad | 2.4289% | 0.4039% | 0.0600% | 2.8928% | 2.8319% | 3.3728% | 4 |
| 26 | Atlantic Avenue | 2.1372% | 0.3513% | 0.0515% | 2.5401% | 2.4918% | 2.9615% | 16 |
| 27 | Ventnor Avenue | 2.0884% | 0.3743% | 0.0564% | 2.5192% | 2.4349% | 2.9371% | 18 |
| 28 | Water Works | 2.2224% | 0.3761% | 0.0562% | 2.6548% | 2.5911% | 3.0952% | 10 |
| 29 | Marvin Gardens | 2.0113% | 0.3698% | 0.0576% | 2.4387% | 2.3449% | 2.8433% | 21 |
| 30 | Jail | 3.7130% | 3.0941% | 2.5784% | 9.3855% | 10.9425% | 10.9425% | 1 |
| 31 | Pacific Avenue | 2.0939% | 0.3706% | 0.0604% | 2.5249% | 2.4412% | 2.9438% | 17 |
| 32 | North Carolina Avenue | 2.1486% | 0.2833% | 0.0450% | 2.4769% | 2.5051% | 2.8878% | 20 |
| 33 | Community Chest (E) | 1.8399% | 0.3327% | 0.0566% | 2.2292% | 2.1451% | 2.5990% | 26 |
| 34 | Pennsylvania Avenue | 2.0388% | 0.2757% | 0.0431% | 2.3576% | 2.3770% | 2.7488% | 23 |
| 35 | Short Line | 1.8806% | 0.3505% | 0.0614% | 2.2925% | 2.1926% | 2.6728% | 25 |
| 36 | Chance (E) | 0.6844% | 0.1154% | 0.0176% | 0.8174% | 0.7980% | 0.9531% | 39 |
| 37 | Park Place | 1.6576% | 0.3429% | 0.0612% | 2.0616% | 1.9326% | 2.4036% | 33 |
| 38 | Luxury Tax | 1.7605% | 0.2564% | 0.0389% | 2.0558% | 2.0525% | 2.3969% | 34 |
| 39 | Boardwalk | 2.0336% | 0.3831% | 0.0695% | 2.4861% | 2.3709% | 2.8986% | 19 |
| Total | 80.0984% | 15.3536% | 4.5480% | 100.0000% | 100.0000% | 116.5896% |
To compute the stationary distribution of spaces (not states: remember, there are 40 spaces and 120 states) at the end of each roll, we just have to add up the three columns — this probability is shown in the end_of_roll column.
For the other two probability measures, we need to condition on the states that occur at the end of a turn, which are all 40 spaces in column 0 (no next turn from doubles) as well as the other two Jail states, excluding all the other states in columns 1 or 2. The probability \( p_0 \) of ending the turn on each roll is approximately 85.77%, the sum of the individual state probabilities.
p0 = ftable[0].sum() + ftable.loc[30, 1] + ftable.loc[30,2]
p0, 1/p0
(0.8577091677010623, 1.16589636400917)
The stationary distribution of spaces at the end of each turn are the first column values divided by \( p_0 \) — except for Jail, where the probability is the sum of the per-roll probabilities divided by \( p_0 \).
The probability of landing on a given space during each turn is the probability of landing on that space per roll, divided by \( p_0 \). This gives a total probability of \( 1/p_0 \approx \) 116.59%, greater than one, but the events are not exclusive: someone could land on Go on the first roll, then land on Income Tax on the second roll, and then St. Charles Place on the last roll, all in the same turn.
Jail is the highest-likelihood space on the board (a 10.94% chance to be in Jail each turn), with Illinois Avenue a distant second (about 3.5% chance to land on Illinois Ave. during a turn), and the Orange properties all in the top ten (St. James Place, Tennessee Avenue, New York Avenue, all with 3.1 – 3.3% chance to land during a turn).

The Dark Blue properties (Baltic and Mediterranean Avenue) are languishing in the 2.3 – 2.4% chance to land during a turn, making them more than 25% less likely to land on than the Orange properties.
We can show these probabilities as bar charts, either in order of spaces on the board, or in descending order of probability of landing on the space in a given turn.
for ifig in range(2):
    f = lambda dataframe: dataframe if ifig == 0 else dataframe.sort_values('rank')
    fig,ax = plt.subplots(figsize=(10,6))
    (f(ftable.iloc[:40])
         [['space','end of roll','end of turn','during turn']]
         .set_index('space')
         .plot.bar(ax=ax, width=0.7))
    ax.set_ylim(0,0.038)
    ax.set_yticks(np.arange(0,0.038,0.001), minor=True)
    ax.grid(axis='y', linewidth=1.0)
    ax.grid(axis='y', which='minor', linewidth=0.5, color='#f0f0f0')
    ax.legend(loc='lower left', framealpha=0.95, labelspacing=0)
    fig.savefig('monopoly_dist_barchart.%d.png' % ifig, dpi=75.88, bbox_inches='tight')


Go, B. & O. Railroad, Free Parking, Reading Railroad, and Water Works round off the top ten, as any Monopoly player who’s done their homework knows.
The Chance spaces are the least likely — even though it’s relatively common to land on them, most of the Chance cards send the player somewhere else.
Checking Your Work: Reducing the Impact of Human Error
The behavior of Monopoly is complex enough that it’s possible to make errors in these calculations. I don’t claim that these numerical results are exactly correct, but I’ve taken reasonable steps to review both the intermediate results (the transition matrix probabilities) and the end results of the stationary distribution, to make sure they match my understanding of the game. For example, those tables I showed earlier, describing state transition probabilities from Go, North Carolina Avenue, the north-side Chance, and Jail. These are easy to review. The end results are also reasonable, given effects of some of the game dynamics: all of the railroads and utilities have slightly elevated chances because of the Chance cards, as do St. Charles Place, Illinois Ave., and Boardwalk (also Chance card destinations), compared to nearby spaces.
I’ve checked my work against two well-known analyses from the 1970s, and my results are off by about 0.1%, which is frustrating. However a third analysis from the 1990s matches the steady-state probabilities of the first two, and it only uses a 40-space state model, which misses some of the numerical behaviors of the game. (See Addenda for a few more comments.)
Interpreting the Results
These probabilities are just interesting numbers until it becomes time to apply them in a real-world scenario: suppose a player owned all the Orange properties and the Green properties, and had \$700 in cash, and was deciding which houses to build. The Orange properties have a slightly higher probability of landing on, but the Green properties have higher rent costs.
Someone can do a computation of the incremental expected value per turn in adding houses:
- Orange properties, one house each (total cost of houses: \$300):
- St. James Place: +\$1.75 (rent from no houses is \$14 and increases with one house to \$70, with a 3.1233% per turn of landing on this space)
- Tennessee Ave.: +\$1.84 (\$14 → \$70, 3.2875% per turn)
- New York Ave.: +\$2.10 (\$16 → \$80, 3.2780% per turn)
- Total Orange increase: +\$5.69 per turn, on average
- Orange properties, two houses each (total cost of houses: \$600):
- St. James Place: +\$5.81 (\$14 → \$200, 3.1233% per turn)
- Tennessee Ave.: +\$6.11 (\$14 → \$200, 3.2875% per turn)
- New York Ave.: +\$6.69 (\$16 → \$220, 3.2780% per turn)
- Total Orange increase: +\$18.61 per turn, on average
- Green properties, one house each (total cost of houses: \$600):
- Pacific Ave.: +\$3.06 (\$26 → \$130, 2.9438% per turn)
- North Carolina Ave.: +\$3.00 (\$26 → \$130, 2.8878% per turn)
- Pennsylvania Ave.: +\$3.35 (\$28 → \$150, 2.7488% per turn)
- Total Green increase: +\$9.41 per turn, on average
So the Green properties have higher expected increase from adding one house than the Orange properties. But houses are more expensive: \$200 each for the Greens and \$100 each for the Oranges.
Orange properties have a higher return on investment, both for adding one house each (less cost for Orange) or for adding \$600 worth of houses (higher return for Orange). At endgame, though, when hotels are built, Green properties bring higher income.
Decisions, Decisions
There are all sorts of calculations you can do if you have a good model of the system.
For example, what happens in each of these cases:
- Someone drops the “Advance to St. Charles Place” card on the floor and it falls under the couch, its absence unnoticed — how does this affect the probability of landing on different spaces?
- Someone lands on Chance and draws a Get Out of Jail Free card — should they hold onto it, or use it and put it back in the deck?
We can model these by altering the probability of drawing cards; in each case, the number of cards decreases by one, from 16 to 15:
class DrawCardProbabilityMissingCards(monopoly.DrawCardProbability):
    def __init__(self, missing_cards):
        self.missing = set(missing_cards)
        super().__init__()
    def include_card(self, card):
        return card not in self.missing

class MonopolyChainNoStCharlesPlace(monopoly.MonopolyChain):
    def initDrawCardProbability(self):
        return DrawCardProbabilityMissingCards([monopoly.Card.CHANCE_ADVANCE_TO_ST_CHARLES_PLACE])

class MonopolyChainNoJailFree(monopoly.MonopolyChain):
    def initDrawCardProbability(self):
        return DrawCardProbabilityMissingCards([monopoly.Card.CHANCE_GET_OUT_OF_JAIL_FREE])

chain_missing_stcharles = MonopolyChainNoStCharlesPlace()
chain_missing_jailfree  = MonopolyChainNoJailFree()

ftable_stcharles = chain_missing_stcharles.get_frequency_table()
ftable_jailfree  = chain_missing_jailfree.get_frequency_table()

ftable_delta = ftable[['space']].copy()
ftable_delta.columns = pd.MultiIndex.from_tuples([('', 'space')])
for baseline_col in 'end of turn', 'during turn':
    ftable_delta[(baseline_col, 'baseline')] = ftable[baseline_col]
    for scenario, ftable_other in [('St. Charles', ftable_stcharles),
                                   ('Out of Jail Free', ftable_jailfree)]:
        ftable_delta[(baseline_col, '\u0394 '+scenario)] = ftable_other[baseline_col] - ftable[baseline_col]

p_total = ftable_delta.sum().to_dict()
p_total[('','space')] = ''
fancy_freq_table_style(ftable_delta).concat(
    fancy_freq_table_style(pd.DataFrame(p_total, index=['Total']))
)
| end of turn | during turn | ||||||
|---|---|---|---|---|---|---|---|
| space | baseline | Δ St. Charles | Δ Out of Jail Free | baseline | Δ St. Charles | Δ Out of Jail Free | |
| 0 | Go | 2.9102% | 0.0317% | 0.0251% | 3.4024% | 0.0387% | 0.0283% |
| 1 | Mediterranean Avenue | 1.9009% | 0.0068% | -0.0104% | 2.3435% | 0.0079% | -0.0096% |
| 2 | Community Chest (S) | 1.7769% | 0.0077% | -0.0075% | 2.0724% | 0.0100% | -0.0093% |
| 3 | Baltic Avenue | 1.9495% | 0.0141% | -0.0136% | 2.3782% | 0.0155% | -0.0128% |
| 4 | Income Tax | 2.1399% | 0.0232% | 0.0021% | 2.5610% | 0.0282% | 0.0016% |
| 5 | Reading Railroad | 2.7220% | 0.0618% | 0.0409% | 3.2703% | 0.0727% | 0.0508% |
| 6 | Oriental Avenue | 2.1036% | 0.0159% | -0.0001% | 2.4887% | 0.0196% | -0.0024% |
| 7 | Chance (S) | 0.7901% | 0.0600% | -0.0881% | 0.9518% | 0.0722% | -0.1055% |
| 8 | Vermont Avenue | 2.1758% | 0.0181% | 0.0052% | 2.5537% | 0.0224% | 0.0028% |
| 9 | Connecticut Avenue | 2.1468% | 0.0189% | 0.0035% | 2.5314% | 0.0244% | 0.0022% |
| 10 | Just Visiting | 2.0761% | 0.0251% | -0.0012% | 2.4976% | 0.0283% | -0.0006% |
| 11 | St. Charles Place | 2.5122% | -0.4114% | 0.0281% | 2.9842% | -0.4887% | 0.0327% |
| 12 | Electric Company | 2.5726% | 0.0516% | 0.0141% | 3.0494% | 0.0593% | 0.0184% |
| 13 | States Avenue | 2.1459% | 0.0305% | -0.0060% | 2.5370% | 0.0224% | -0.0072% |
| 14 | Virginia Avenue | 2.4134% | 0.0076% | -0.0073% | 2.8276% | 0.0122% | -0.0070% |
| 15 | Pennsylvania Railroad | 2.6232% | 0.0239% | 0.0141% | 3.0740% | 0.0203% | 0.0168% |
| 16 | St. James Place | 2.6888% | -0.0225% | 0.0001% | 3.1233% | -0.0179% | 0.0005% |
| 17 | Community Chest (W) | 2.3116% | -0.0239% | 0.0024% | 2.6759% | -0.0304% | 0.0021% |
| 18 | Tennessee Avenue | 2.8374% | -0.0550% | 0.0060% | 3.2875% | -0.0517% | 0.0063% |
| 19 | New York Avenue | 2.8465% | -0.0225% | 0.0205% | 3.2780% | -0.0307% | 0.0210% |
| 20 | Free Parking | 2.8215% | -0.0368% | 0.0089% | 3.2934% | -0.0355% | 0.0095% |
| 21 | Kentucky Avenue | 2.5834% | -0.0176% | 0.0054% | 3.0479% | -0.0306% | 0.0072% |
| 22 | Chance (N) | 1.0337% | 0.0591% | -0.1122% | 1.2183% | 0.0713% | -0.1325% |
| 23 | Indiana Avenue | 2.5143% | -0.0076% | 0.0044% | 2.9932% | -0.0221% | 0.0064% |
| 24 | Illinois Avenue | 2.9514% | 0.0129% | 0.0351% | 3.4924% | 0.0195% | 0.0380% |
| 25 | B. & O. Railroad | 2.8319% | 0.0025% | 0.0223% | 3.3728% | 0.0048% | 0.0278% |
| 26 | Atlantic Avenue | 2.4918% | -0.0187% | 0.0003% | 2.9615% | -0.0189% | -0.0021% |
| 27 | Ventnor Avenue | 2.4349% | -0.0134% | -0.0067% | 2.9371% | -0.0156% | -0.0045% |
| 28 | Water Works | 2.5911% | -0.0003% | 0.0067% | 3.0952% | 0.0006% | 0.0067% |
| 29 | Marvin Gardens | 2.3449% | -0.0011% | -0.0123% | 2.8433% | -0.0043% | -0.0107% |
| 30 | Jail | 10.9425% | 0.0762% | 0.0731% | 10.9425% | 0.0762% | 0.0731% |
| 31 | Pacific Avenue | 2.4412% | 0.0027% | -0.0038% | 2.9438% | 0.0002% | -0.0025% |
| 32 | North Carolina Avenue | 2.5051% | -0.0013% | 0.0017% | 2.8878% | -0.0004% | -0.0005% |
| 33 | Community Chest (E) | 2.1451% | 0.0079% | 0.0074% | 2.5990% | 0.0080% | 0.0095% |
| 34 | Pennsylvania Avenue | 2.3770% | -0.0047% | 0.0040% | 2.7488% | -0.0029% | 0.0016% |
| 35 | Short Line | 2.1926% | -0.0029% | 0.0027% | 2.6728% | -0.0035% | 0.0033% |
| 36 | Chance (E) | 0.7980% | 0.0521% | -0.0886% | 0.9531% | 0.0624% | -0.1054% |
| 37 | Park Place | 1.9326% | -0.0021% | -0.0005% | 2.4036% | -0.0022% | 0.0000% |
| 38 | Luxury Tax | 2.0525% | -0.0008% | -0.0002% | 2.3969% | 0.0002% | -0.0029% |
| 39 | Boardwalk | 2.3709% | 0.0321% | 0.0246% | 2.8986% | 0.0375% | 0.0302% |
| Total | 100.0000% | 0.0000% | 0.0000% | 116.5896% | -0.0203% | -0.0186% | |
These modifications have the largest effect on St. Charles Place (if the Advance to St. Charles Place card is missing), which drops by 0.49% per turn, and the Chance cards (if someone holds onto the Get out of Jail Free card), which drop by about 0.1% per turn, since there is one less Chance card that doesn’t move the token. The other probabilities change by a much smaller amount, a fraction of a percent; at most it’s about 0.03% – 0.04% increase for the properties that Chance cards take you, topping out at 0.05% – 0.07% increase for landing on Reading Railroad.
For example, let’s say you have a hotel on each of the Red properties. Should you hold onto the Get out of Jail Free “Chance” Card to manipulate these chances?

Your expected change in income per turn for holding onto the Get out of Jail Free “Chance” card, per opponent, is:
- Kentucky Avenue: +\$0.0756 = +0.0072% per turn × \$1050
- Indiana Avenue: +\$0.0672 = +0.0064% per turn × \$1050
- Illinois Avenue: +\$0.418 = +0.0380% per turn × \$1100
- Total: +\$0.56 per turn
If you have two opponents, you can expect to generate an extra \$1.12 per turn if you hold onto the Get out of Jail Free card, which is something, but effectively negligible.
You could also use this card to save the \$50 you spend getting out of Jail on the third turn — the probability of this is on the order of 2.15% (2.578% chance of being in Jail on the third turn, from one of the tables above, times a 5/6 chance of not rolling doubles), which will save you on average \$1.074 per turn.
The Get out of Jail Free card has value, but it’s small however you want to use it.
Other Insights
Static vs. Dynamic Analysis
Transition matrix analysis is a form of static analysis, and Monte Carlo simulation is a form of dynamic analysis. Static analysis essentially involves prediction and hypothetical thinking: what could happen in certain cases, according to these rules? Whereas dynamic analysis essentially involves trying to observe things as they happen — whether in simulation or real life.
I didn’t bother trying to run a Monte Carlo simulation of Monopoly, simply because the number of trials I’d need to figure out the per-space probabilities is huge. Here’s a simplification where we run five trials of rolling dice a million times to move a token around a 40-space board, where landing on space 30 sends you to space 10:
rolls = 1000000
trials = 5
nspaces = 40
history = np.zeros((nspaces, trials))
r = np.random.RandomState(seed=123)
for i in range(trials):
    pos = 0
    for _ in range(rolls):
        dice = r.randint(6, size=2) + 1
        pos = (pos + dice[0] + dice[1]) % nspaces
        if pos == 30:
            pos = 10
        history[pos,i] += 1
fig,ax = plt.subplots(figsize=(10,7))
ax.plot(history/rolls, '.', markersize=5)
ax.set_ylim(0.02,0.051)
ax.set_xlim(-0.5,39.5)
ax.grid(True)

The frequencies of landing on each space are probably accurate to within 0.1% or so — again, that’s with five trials of a million rolls. Every additional digit of precision costs a runtime increase of 100×.
More or less the same dynamics of Monopoly: space 30 casts a “probability shadow”, reducing chances of landing on the spaces that follow it (32 – 39, 0 – 9, 11 – 13), since landing on space 30 diverts the token to space 10. Which then raises the chances of landing on spaces that follow it (12 – 29, 31 – 33).
Static analysis through transition matrix analysis would give you the exact chances of landing on each space, but it works for systems that are simple, or can be broken down into simple independent subsystems. With more complicated systems the complexity blows up to be intractable in static analysis. Imagine we want to take into account the real behavior of the Community Chest and Chance piles, where successive cards drawn from the pile are not independent; for example, the 1950s rules state:
LANDING on “CHANCE” or “Community CHEST”
A player takes the top card from the pack indicated and after following the Instructions printed thereon, returns the card face down to the bottom of the pack. The “Get Out of Jail Free” card, however, is retained until used. After being used, it is returned to the bottom of the pack. This card may be Sold by a player to another player at a price agreeable to both.
This means that the order in which the cards are drawn is fairly repetitive in practice, although technically there are 16! = 20,922,789,888,000 = just under 21 trillion possible orderings of each of the two piles, raising the number of states from 120 to something like 5.2 × 1028, which is not directly amenable to transition matrix analysis. Too bad.
Or you approximate the system with some simplification (like assuming card draws are independent, or the ultrasimple 40-space system here with space 30 leading to space 10) to make it amenable to static analysis.
When the number of distinct states is large, dynamic analysis still remains tractable. It’s just that you have to treat the numbers as estimates.
I’ve run into similar tradeoffs trying to estimate CPU cycle time for code compiled on certain embedded processors. It was easier when typical embedded processors ran a certain fixed number of clock cycles for each instruction. Then you could just count total cycles for branchless sequences of instructions, or consider a tree of alternatives for a firmware routine that had a low number of branches. This is static analysis, modeling the CPU cycle count, and as long as the number of branches isn’t high, and there aren’t other weird factors like caching, then it’s quite accurate. But if you’re using a dsPIC33A, or an ARM M7, caches are present, and it’s going to be really hard to use static analysis to predict the resulting range of cycle counts, unless you have a good model of the cache mechanism.
Or you could profile the same code, measuring a CPU cycle counter before and after the routine in question. This is dynamic analysis, which can work in simple cases, but if there are lots of branches then you have to worry about covering all the alternative paths through a function. It could be that you missed a possibility, and it takes an extra 86 clock cycles in this one weird rare case.
Heuristics
We can take the Monopoly probabilities and condense them down to a few rules:
- Ending on Jail has the highest chances of any space.
- Landing on the Orange and Red properties (especially Illinois Ave) have the next highest chances in general, because getting out of Jail sends you right toward them.
- Landing on Go, Reading Railroad, Pennsylvania Railroad, and B & O Railroad, and the two utilities have increased chances because of the Chance and Community Chest cards.
- Landing on the Green, Dark Blue, and Dark Purple properties is less common, because landing on Go to Jail catches players sometimes and keeps a player from reaching the spaces beyond Go to Jail as often. (Boardwalk is the exception, because of the Chance card that sends a player there.)
You don’t need to model the exact probabilities to win at Monopoly; you can use this kind of a shortcut to avoid having to overanalyze the situation. This is known as a heuristic; Gerd Gigerenzer and Wolfgang Gaissmaier proposed the following definition:
A heuristic is a strategy that ignores part of the information, with the goal of making decisions more quickly, frugally, and/or accurately than more complex methods.
Getting to a heuristic may require some analysis (whether you do it, or you rely on someone else’s), but applying it as an approximation is generally much easier than recalling the full model and results every time.
Wrapup
We analyzed the frequency of landing on the different spaces on the Monopoly board, using Markov chain transition matrix analysis. A Markov chain is a probabilistic state machine where the probability of moving from one state to another depends only on the source state in each step. In general the method goes like this:
- Define the problem.
- Define the states.
- Calculate the state transition matrix for each pair of states.
- Find the stationary distribution, using eigenvalue/eigenvector analysis, or repeated matrix multiplication (power iteration)
Don’t forget to check your work, and in general this type of static analysis is tractable only where the number of states is fairly small — otherwise, dynamic analysis such as Monte Carlo simulation is a more practical alternative that produces approximate results.
And have fun! Monopoly loses that quickly if it becomes overcompetitive.
Addenda
References
There are several well-known sources that have performed a matrix analysis of this type. Notable are the first three listed below.
- Robert Ash and Richard Bishop, Monopoly as a Markov Process, Mathematics Magazine, 1972.
- Irvin R. Hentzel, How to Win at Monopoly, Saturday Review, March 1973.
- Truman Collins, Probabilities in the Game of Monopoly, 1997.
- Ivars Peterson, Monopoly Dollars and Sense, June 1997.
- Robert Ash and Richard Bishop, Monopoly as a Markov Process, self-published revised manuscript, 2003.
- Benjamin Bernard, *Monopoly — An Analysis using Markov Chains, April 2017.
© 2026 Jason M. Sachs, all rights reserved.